Quick summary
- Databricks puts sub-second Feature Store freshness at the center of feature serving. The reminder for teams is that a low-code workflow only helps when inference features still match operational reality.
- Strong offline model results do not guarantee good decisions when inference features are stale or differ from training features.
- Inventory online features, set a data-age threshold for each, and test fallbacks when a feature is unavailable.
What happened
No-code and low-code tools can shorten model creation, but they do not solve feature serving by themselves. Databricks highlights sub-second freshness for its Feature Store, a concern that matters when a decision depends on the current state of a system.
That means “data to dashboard” is not the entire ML architecture. For online use cases, inference data is an operational product in its own right.
What does feature freshness mean?
Features are model inputs: transaction signals, user state, or operational measurements, for example. When a served value no longer represents the state relevant to a decision, a prediction can become less useful even if training was sound.
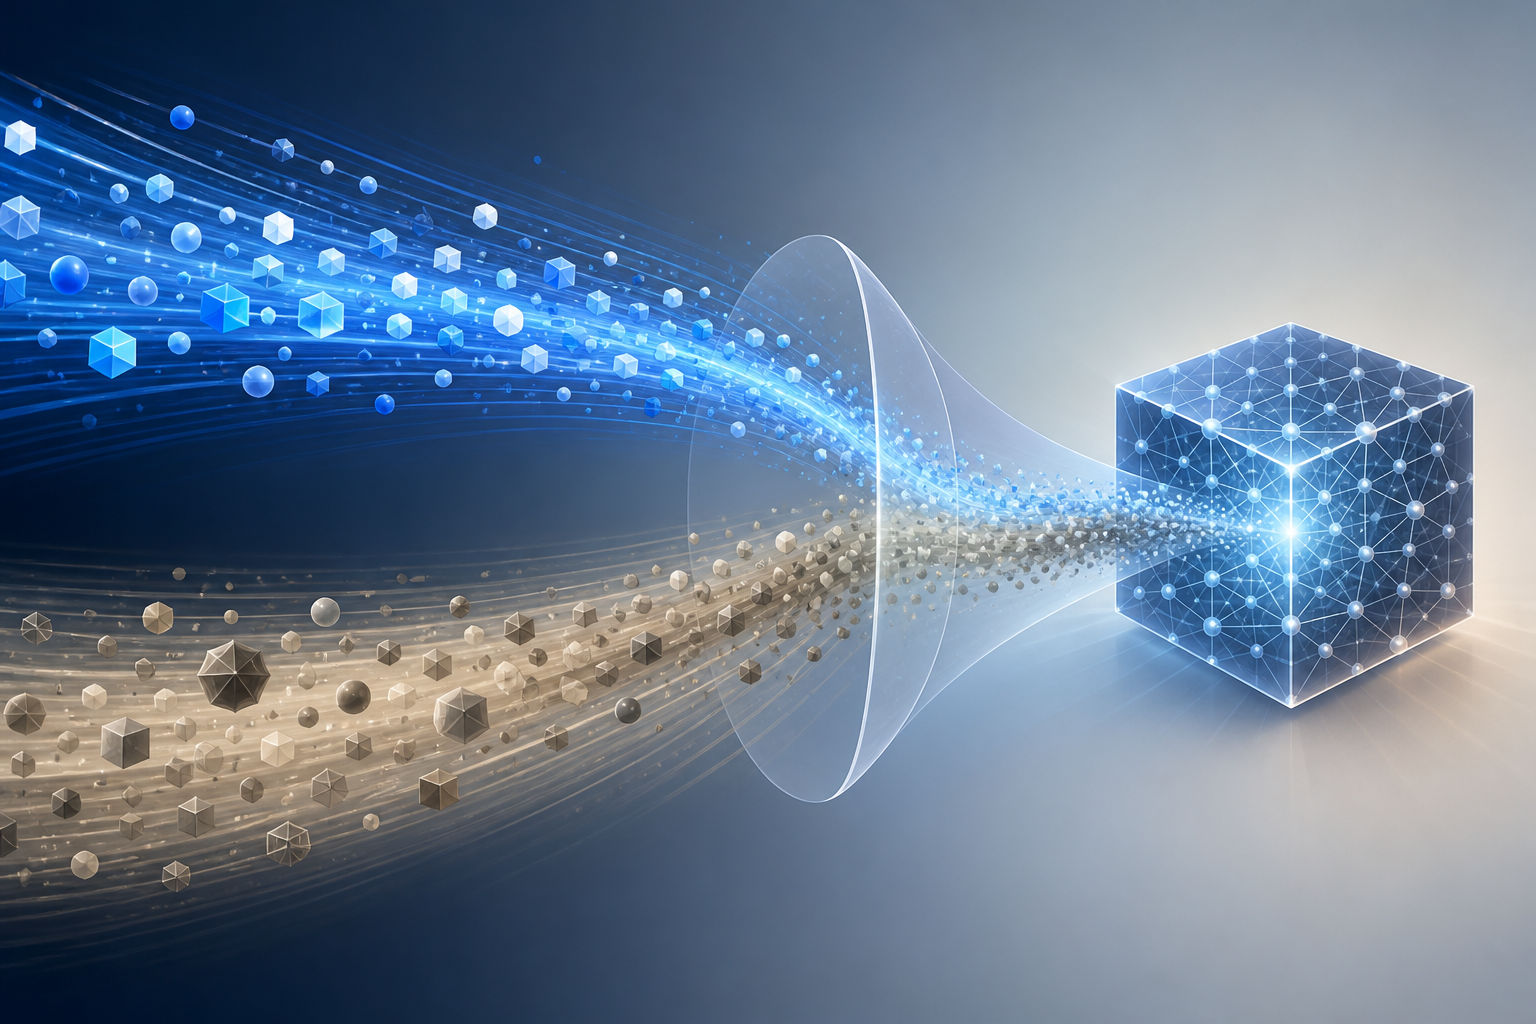
The Databricks discussion of sub-second Feature Store freshness makes the important distinction: freshness is a serving-path property, not merely a property of an offline table.
The gap between a demo and an online system
AWS's transaction-data, visual-transformation, Canvas, and dashboard workflow is a useful pattern for analysis and review processes. If a model must react while an interaction is occurring, though, teams need to decide which features require rapid updates, who owns them, and what happens when they cannot be retrieved.
Do not infer that every workload needs, or will achieve, sub-second freshness. The appropriate SLA should follow the decision being made, not a platform capability.
Architecture questions to answer
- Which features are shared between training and inference?
- What latency is acceptable for each feature?
- Is feature age observed at prediction time?
- What is the fallback for delayed, missing, or failed feature retrieval?
Start with observability
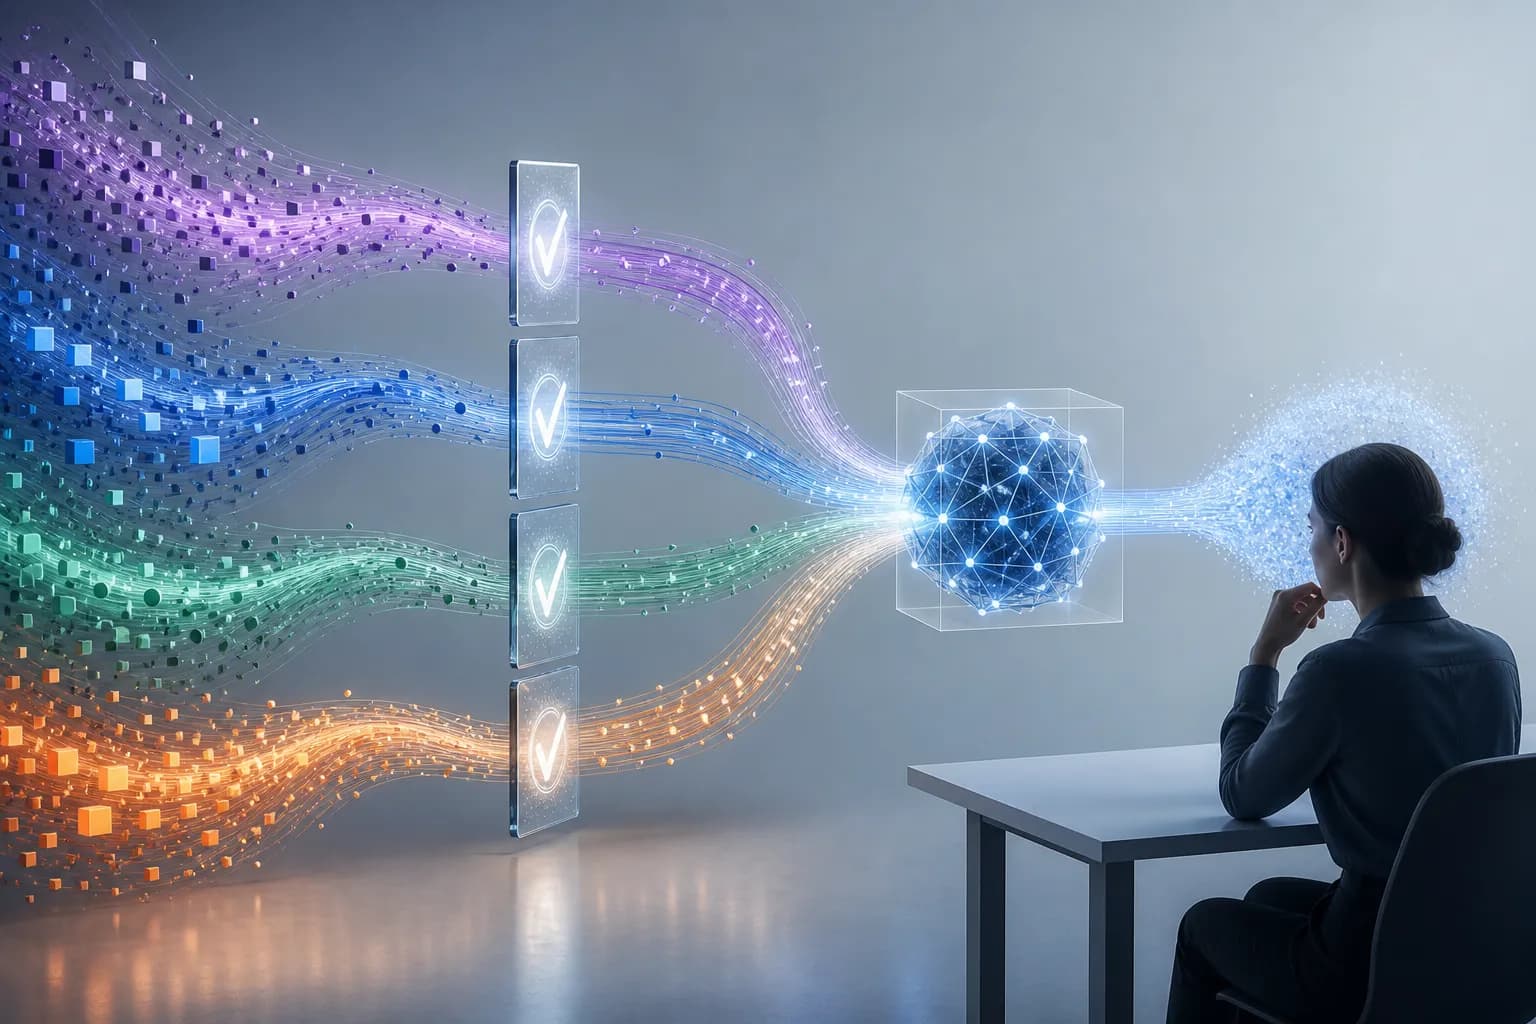
Before optimizing speed, measure feature age, missingness, and divergence between training and served data. A dashboard may show outcomes; feature observability helps establish whether the model received the right context when it made a prediction.
In 5 Minutes
- Databricks highlights Feature Store serving with sub-second freshness.
- Freshness is an inference-serving concern, not just a warehouse concern.
- Online use cases need feature SLAs, fallbacks, and monitoring.
- Measure feature age and completeness before chasing performance.
Sources
- Build a no-code ML workflow with Snowflake, Amazon SageMaker Canvas and Amazon Quick – Part 1: Setting up your Snowflake environment
- Build a no-code ML workflow with Snowflake, Amazon SageMaker Canvas and Amazon Quick – Part 2: Data preparation and model building with Amazon SageMaker Canvas
- Build a no-code ML workflow with Snowflake, Amazon SageMaker Canvas and Amazon Quick – Part 3: Visualizing insights with Amazon Quick Sight
- How Databricks Feature Store serves features with sub-second freshness
- Using AI_Functions in Your Data Warehouse: Top Use Cases
Why developers should care
Strong offline model results do not guarantee good decisions when inference features are stale or differ from training features.
Recommended action
- 1Inventory online features, set a data-age threshold for each, and test fallbacks when a feature is unavailable.