Quick summary
- AWS outlines a no-code workflow that carries Snowflake data through visual preparation, model training, and stakeholder dashboards. It is a practical pilot pattern for teams trying to shorten the path from operational data to decisions.
- No-code ML can accelerate prediction prototypes for data and business teams, but it does not remove the need for data controls, evaluation, and operational ownership.
- Pilot a human-reviewed classification workflow and define data, model, and dashboard acceptance criteria before building it.
What happened
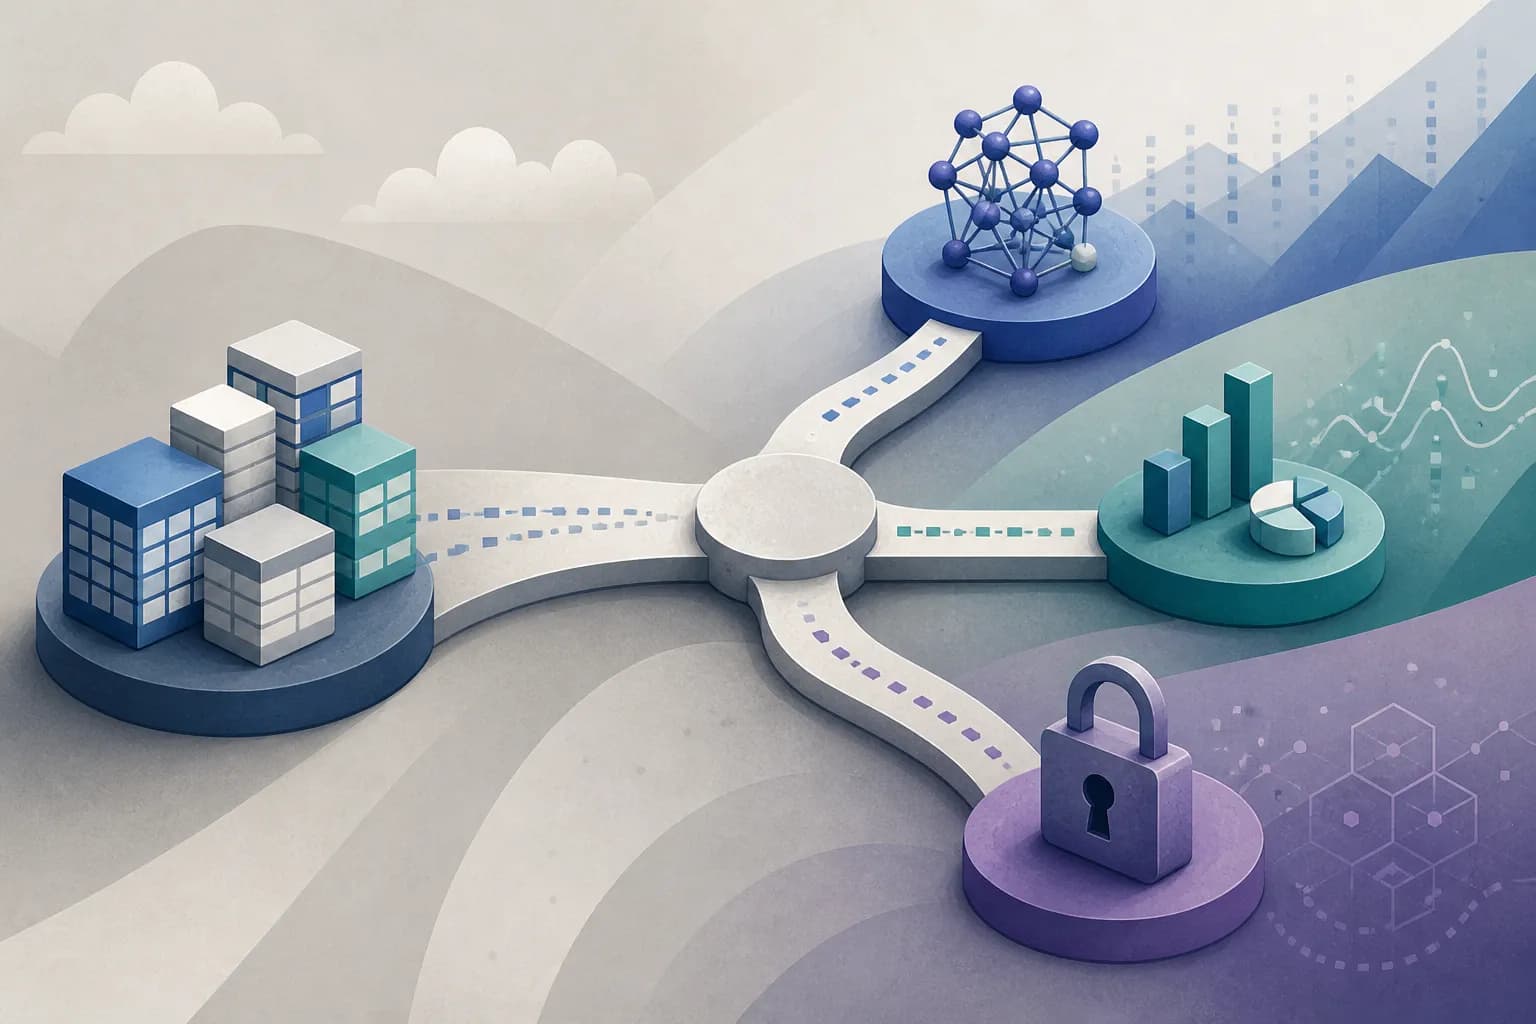
Machine learning does not always have to begin with notebooks and hand-built pipelines. AWS describes a no-code path from Snowflake transaction data to a fraud-detection model and a dashboard for decision-makers.
The useful part is not any one product. It is the connection of steps that are often owned separately: data access, preparation, training, and communicating results.
What does the workflow cover?
The first installment sets up AWS and Snowflake for a fraud-detection use case. AWS frames the problem around operational datasets in sectors such as healthcare, retail, and life sciences that are difficult to turn into predictions.
In its data-preparation and model-building walkthrough, AWS connects SageMaker Canvas to Snowflake, uses Data Wrangler visual transformations and joins on transaction data, then trains an XGBoost fraud-detection model. The described flow requires no ML code.
A dashboard is an operational endpoint
The final installment imports Canvas predictions into Amazon Quick Sight for interactive dashboards. AWS also describes generative BI questions in natural language and AI-generated executive summaries.
Connecting predictions to BI tests a more important question than whether a model can train: can the intended user understand and act on its output? A natural-language answer or generated summary, however, is not proof that a prediction is correct.
Where engineering ownership remains essential
No-code is not no-design. Teams should establish Snowflake access controls, a fraud-label definition, handling for sensitive data, and an evaluation dataset before results reach an operational process.
Start with a human-reviewed decision, retain the data and transformation configuration used for each run, and compare the pilot with the existing workflow. Those controls make a visual tool an auditable accelerator rather than a new black box.
Choose a constrained first use case
A classification problem with historical data and a reasonably clear outcome is a strong candidate. Flagging transactions for review is a safer first test than automatically making customer-impacting decisions.
In 5 Minutes
- AWS presents a Snowflake → Canvas/Data Wrangler → Quick Sight fraud workflow.
- Canvas can visually prepare, join, and train an XGBoost model without ML code.
- Dashboards and natural-language BI can bring predictions to business users.
- Data controls, evaluation, and human review remain engineering responsibilities.
Sources
- Build a no-code ML workflow with Snowflake, Amazon SageMaker Canvas and Amazon Quick – Part 1: Setting up your Snowflake environment
- Build a no-code ML workflow with Snowflake, Amazon SageMaker Canvas and Amazon Quick – Part 2: Data preparation and model building with Amazon SageMaker Canvas
- Build a no-code ML workflow with Snowflake, Amazon SageMaker Canvas and Amazon Quick – Part 3: Visualizing insights with Amazon Quick Sight
- How Databricks Feature Store serves features with sub-second freshness
- Using AI_Functions in Your Data Warehouse: Top Use Cases
Why developers should care
No-code ML can accelerate prediction prototypes for data and business teams, but it does not remove the need for data controls, evaluation, and operational ownership.
Recommended action
- 1Pilot a human-reviewed classification workflow and define data, model, and dashboard acceptance criteria before building it.