Quick summary
- Recent case studies show that effective web caching depends on more than cache-hit ratio. Data layout, object compression, CDN economics, and traffic shape all need measurement before a change is scaled.
- A small per-entry saving can have fleet-wide infrastructure impact, while a poorly matched CDN can add latency or cost. Engineering teams should treat caching as a resource system rather than a default performance switch.
- Baseline one important cache using latency, hit rate, memory per entry, storage, and serving cost, then trial one layout or compression change on a limited scope before fleet-wide rollout.
What happened
Caching is often treated as the obvious way to reduce latency and origin load. Recent examples sharpen the question: not simply whether to cache, but how much memory each entry consumes, which objects deserve storage, and whether the extra delivery layer produces a measurable benefit.
Two optimization paths stand out: reducing overhead in cache data structures and compressing objects inside the cache tier. At the same time, independent developer experience shows that adding a CDN can still make a site slower when network paths, hit rates, and economics do not match the workload.
Why is cache-hit ratio not enough?
Hit ratio shows how often a request is served from cache, but it does not describe total system efficiency. A cache with a high hit rate may still consume excessive RAM, use storage poorly, or add an unnecessary network hop for much of its audience.
The account of a CDN cache making a website slower is a practical warning that delivery architecture needs measurement. A CDN can help when users are far from the origin, objects are reused, and cache keys remain stable. Its benefit may be limited when traffic is close to one server or most responses cannot be reused.
A dashboard containing only hits and misses is therefore incomplete. A useful baseline may combine end-to-end latency, origin time, memory per entry, storage use, eviction rate, and serving cost. That is an analytical recommendation rather than a universal mandatory metric set.
How can cache layout change the memory equation?
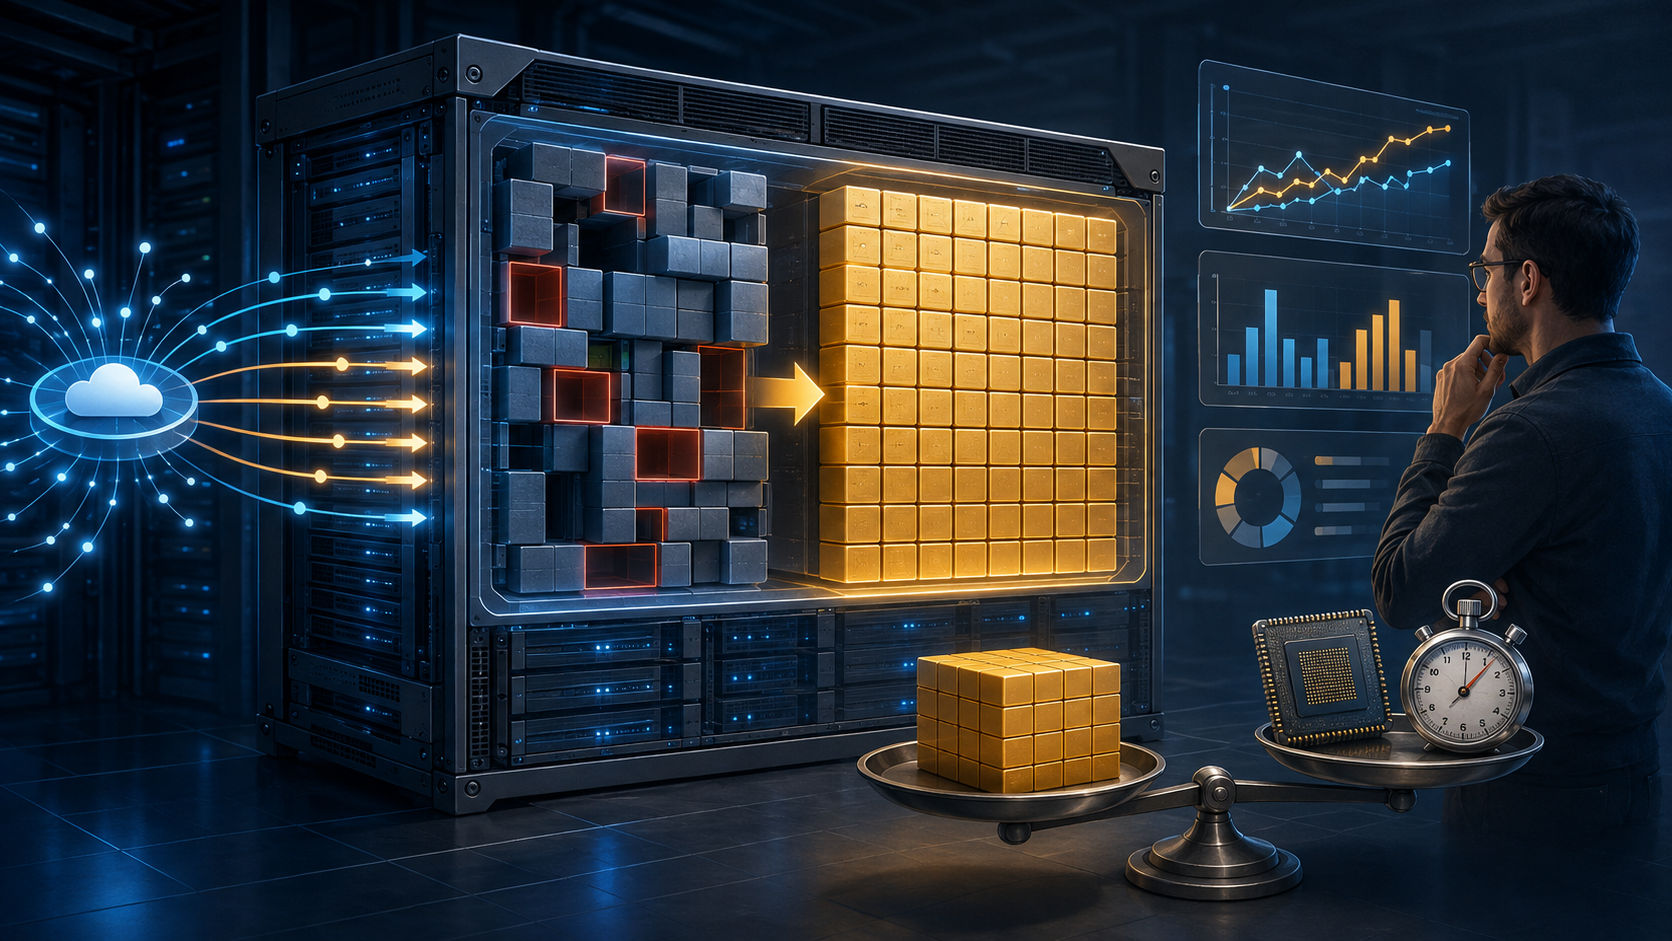
Cloudflare says it made five Rust-level optimizations to the layout of Big Pineapple's DNS cache. According to the company's 1.1.1.1 cache case study, the work reduced memory per entry by 56% and freed approximately 100 TB across its fleet.
The broader lesson is not limited to the headline total. When a structure is replicated across a very large number of entries, padding, allocations, or per-entry metadata can become a meaningful part of the RAM budget. Object-level profiling can expose costs that adding larger machines would merely hide.
Teams using Rust or another systems language should measure actual structure sizes rather than infer them from the sum of field sizes. Inspect memory representation, allocation count, optional values, and metadata retained for rare cases. Any layout change still needs a representative benchmark because a smaller structure does not automatically guarantee faster access.
What does compression inside the cache trade away?
Another path is to increase usable capacity without adding hardware. Cloudflare prototyped Zstandard cache compression in Pingora to explore whether the same infrastructure could hold more content. The company frames the potential at petabyte scale, but this is evidence from a prototype direction, not a default saving that other systems should assume.
Compression shifts part of the problem from storage to CPU and latency. The result depends on data compressibility, reuse frequency, compression and decompression cost, and coordination with already encoded content variants. Objects that are already efficiently compressed may offer less value than text or formats with substantial redundancy.
A controlled test should segment objects by content type, size, and popularity. Operators can compare storage bytes saved with CPU time, tail latency, and changes in eviction behavior. Expansion makes sense only when total cost per request improves or the added effective capacity addresses a known constraint.
How should developers make cache decisions?
Start by naming the objective: lower latency, origin protection, reduced bandwidth, or more retained objects. A policy designed for public images will not necessarily fit DNS data, personalized APIs, or rapidly changing content. Even options such as the open-source wsrv.nl image CDN should be assessed against the actual workload and operational limits, not selected merely because they carry a CDN label.
Next, test against a representative data set or a controlled share of traffic. Record the baseline first, watch resource use alongside hit rate, and segment results by geography, content class, and object size. For image services, plan limits and quotas are also architectural inputs; coverage of image optimization cap decisions illustrates how caching choices can connect directly to platform economics.
Finally, give cache policy an owner, rollback thresholds, and a review cycle. This is a change-governance problem similar to designing a governed control plane: policy is useful only when a team knows who can modify it, how impact is observed, and how a safe state is restored.
Conclusion
- Do not use cache-hit ratio as the sole measure of caching efficiency.
- Small per-entry overhead can become a large fleet-wide memory cost.
- Cache compression can save storage but must be balanced against CPU and latency.
- Benchmark the real workload, preserve a baseline, and define rollback before scaling.
Related reading
- Ventura React: Is this lightweight component library still fit for new projects?
- Nova MCP turns Cursor and Claude into a product-building team
- Ansible Automation Orchestrator: Designing a Governed Control Plane
Sources
- How we saved 100 terabytes of memory by optimizing 1.1.1.1’s DNS cache
- 1.1.1.1 DNS 캐시 최적화로 메모리 100TB 절감
- wsrv.nl - 무료 오픈소스 이미지 CDN
- I Added a CDN Cache to My Site and It Got Slower. Here's the Math I Should Have Done First.
- How we could save petabytes of cache storage with Zstandard and Pingora
- What to Do if Your Site Is About to Hit Vercel's Free Image Optimization Cap
Why developers should care
A small per-entry saving can have fleet-wide infrastructure impact, while a poorly matched CDN can add latency or cost. Engineering teams should treat caching as a resource system rather than a default performance switch.
Recommended action
- 1Baseline one important cache using latency, hit rate, memory per entry, storage, and serving cost, then trial one layout or compression change on a limited scope before fleet-wide rollout.