Quick summary
- A capable, economical model—including DeepSeek for suitable workloads—is not automatically production-grade. Reliability comes from the harness around it: tool routing, context and memory, state recovery, evaluation, observability, permissions, safety guardrails, and inference serving.
- Model selection affects cost and quality, but the harness determines whether a system can be operated safely, measured meaningfully, and recovered when it fails. Teams should evaluate an entire workflow lifecycle, not token prices or benchmark scores alone.
- Within two weeks, implement a minimal gateway for one workflow: request-level traces, token and tool-call limits, least-privilege capabilities, a checkpoint before write actions, and an evaluation suite that includes tool failure and prompt injection. Only then compare DeepSeek with alternatives on cost per successful outcome.
What happened
A capable open model with attractive economics can be a useful component of an AI product. But a model alone does not make a production-grade system. Once it must search for information, call tools, access customer data, resume interrupted work, or produce outputs with business consequences, real-world quality depends on the harness: the system around the model.
Editorial thesis: for DeepSeek, as for any other model, model capability and economics become operational value only when a harness provides routing, context, memory, state recovery, evaluation, observability, permissions, safety guardrails, and inference serving. This is an architectural conclusion, not a claim that DeepSeek built, uses, or endorses any particular harness.
What the sources verify—and what this article infers
Verified source facts: Vercel’s report says that DeepSeek surpassed Google in volume on Vercel in August while cost per token fell 13.6%; it associates the movement with greater open-weight-model volume and more complex use cases. A supplied guide to vLLM discusses serving and scaling inference for agents. Meta has also published examples of a multi-stage ranking architecture and says its GEM training work doubled training efficiency for an LLM-scale ads foundation model.
Editorial inference: those signals do not establish that one model, provider, or architecture fits every workload. They support a narrower operational conclusion: as traffic and automation increase, cost, latency, reliability, and risk no longer reside in a single API call. They need to be managed through a shared harness.
What a harness is in an AI system
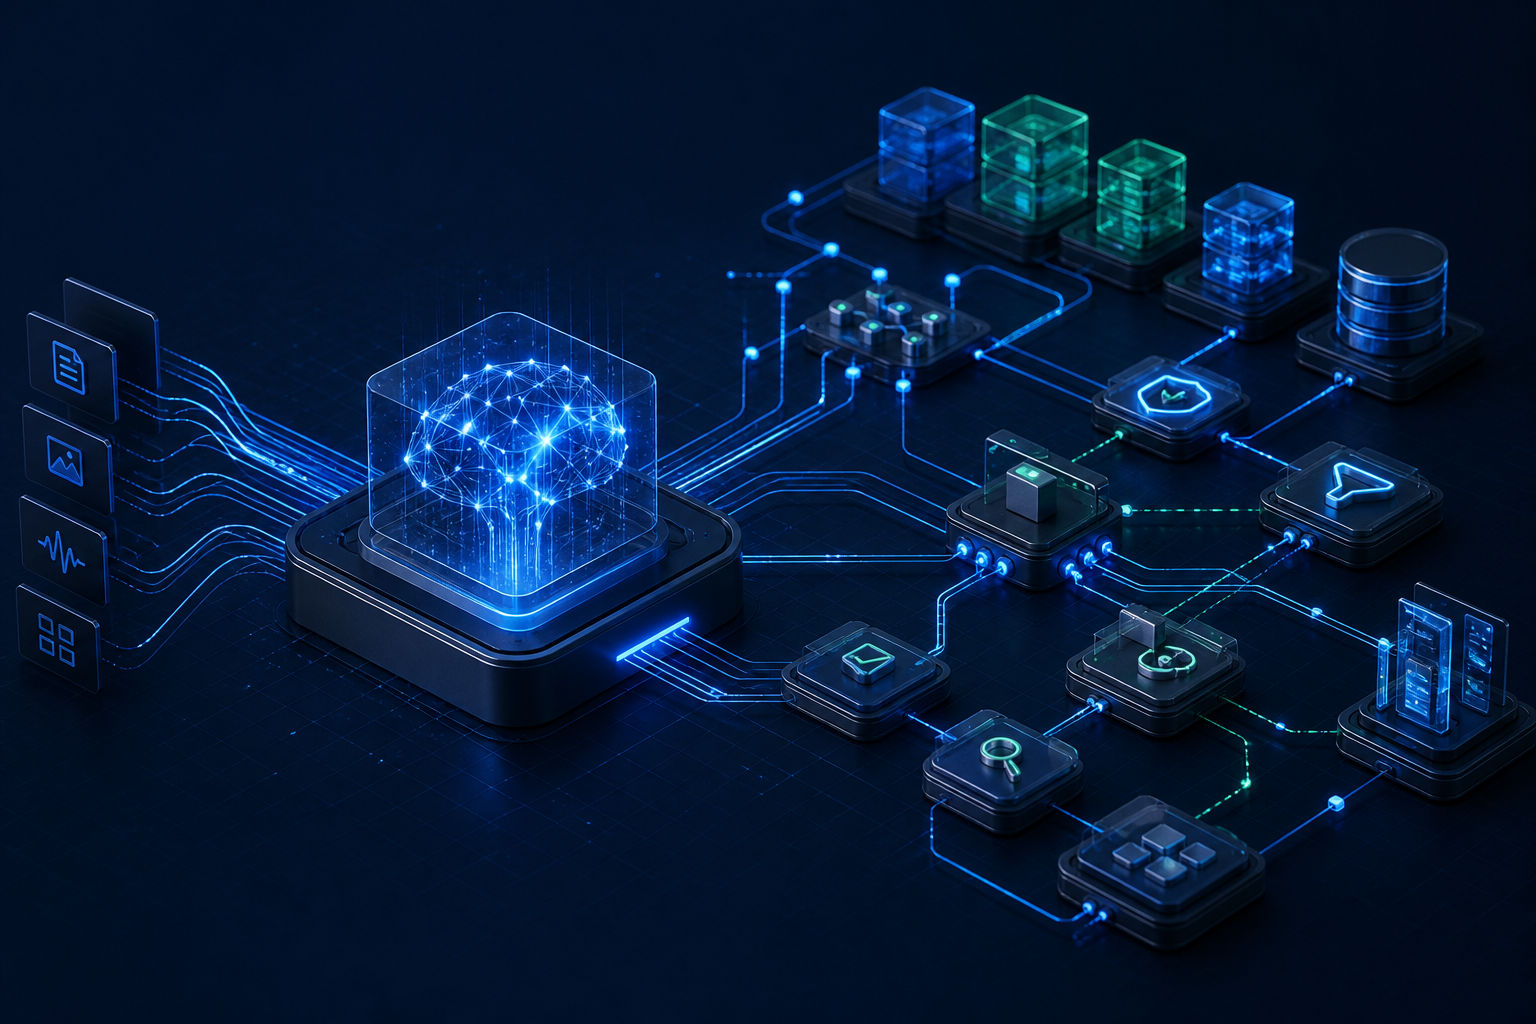
A harness is the collection of software and operational mechanisms that turns probabilistic model output into a bounded, stateful, testable process. It is not synonymous with a longer prompt, one agent framework, or self-hosting. A harness can sit before, after, and around any model API or self-hosted endpoint.
This aligns with Pulumi’s argument for building a harness rather than only tuning prompts: in real engineering environments, instructions, hooks, skills, tools, and feedback loops often materially shape outcomes. The production extension is important: a harness must govern not only how a model reasons, but also how the system authorizes, measures, retries, and fails safely.
Eight capabilities that make a model production-grade
1. Model and tool routing
Not every request needs the same model or the same level of access. The harness should classify work first: simple queries, structured extraction, document summarization, multi-step reasoning, and tool-mediated action. It can then select the appropriate model, prompt template, token limit, toolset, and synchronous or asynchronous execution mode.
This is an architectural inference from model-economics signals, not a DeepSeek-specific prescription. Vercel’s report shows that model mix and volume can move quickly. A routing layer lets teams run controlled experiments rather than permanently wiring a product to one execution path.
2. Disciplined context and memory
Useful context does not mean placing all history into a prompt. The harness must determine which data sources are permitted, which facts are current, what must be cited, and what personal data must be removed or masked. Long-term memory needs retention policies, tenant boundaries, expiry rules, and deletion mechanisms.
In practice, separate at least three layers: short-lived session state; verified task facts; and explicitly consented user memory. Each item should have provenance, creation time, and an access policy. Without those properties, a system cannot reliably explain why a model knew something or prevent data from leaking across users.
3. State, checkpoints, and recovery
Multi-step agents encounter timeouts, tool failures, changing data, and human-approval requirements. The harness should persist workflow state under a durable identifier: the objective, normalized inputs, tools already called, intermediate results, prompt and model versions, and approved decisions.
Make tool operations idempotent where possible. On retry, the system must know which action has already completed so it does not send duplicate email, create duplicate support tickets, or execute duplicate transactions. For externally consequential operations, checkpoint before execution and require confirmation after the model proposes an action.
4. Evaluation before and after deployment
General benchmarks do not replace evaluation on the real task. Build a representative test set containing ordinary inputs, missing data, ambiguous requests, prompt injection, tool failures, and high-consequence cases. Score output quality and process behavior: did the model choose the correct tool, respect permissions, cite the right source, and stop at the right point?
Run evaluations when changing a model, prompt, tool schema, retrieval index, or serving configuration. Metrics should connect to successful workflow outcomes, not token consumption alone. A less expensive model may be more costly in practice if it raises retries, escalation to a stronger model, or manual correction.
5. Observability and auditability
Every run needs an end-to-end trace: model version, provider or endpoint, input and output tokens, queue and inference latency, tool calls, retries, cache hits, errors, estimated cost, and final outcome. Logs should avoid retaining unnecessary secrets and personal data while preserving enough authorized evidence to reconstruct an incident.
Track p50 and p95 latency, tool-error rate, workflow-completion rate, cost per successful outcome, human-intervention rate, and safe-refusal rate. An aggregate AI-spend dashboard cannot show which pipeline is producing retries or permission failures.
6. Least-privilege permissions and approval
A model should not receive broad credentials directly. The harness should issue short-lived capabilities constrained by tenant, task, dataset, and time. A tool gateway should validate input schemas, enforce allowlists, apply rate limits, and write audit events before calling external systems.
Distinguish read operations, reversible writes, and irreversible actions. Transfers of money, deletion of data, access changes, or bulk communication need approval policies that are independent of the model’s own conclusion.
7. Safety guardrails and escape paths
Guardrails should not be only a sentence in a system prompt. They belong at multiple layers: input filtering; permission-aware data retrieval; tool-parameter validation; detection of prohibited content or actions; cost and time limits; and an escalation path to a person or a degraded experience.
No guardrail eliminates all risk. Prompt injection, untrustworthy retrieved material, and variable model behavior remain design assumptions. A robust system must therefore be able to refuse, defer, or request verification rather than compel the model to complete every request.
8. Inference serving and operational reliability
Serving determines whether policies remain enforceable under load: concurrency limits, queues, batching, caching, timeouts, rate limits, fallback, version rollout, and tenant isolation. vLLM is one commonly discussed option for LLM serving; the supplied source discusses it in the context of scaling agent inference. That does not mean self-hosting is always superior to a managed API.
Compare total cost of ownership: GPUs, idle capacity, power, cooling, security, on-call labor, and recovery objectives—not API and GPU prices alone. These physical constraints are explored further in this discussion of GPUs, power, cooling, and data centers as AI infrastructure decisions.
A practical implementation path
- Choose one narrow workflow: prefer a task with clear value, defined inputs, and a measurable result.
- Define the workflow contract: specify inputs, structured outputs, permitted tools, token and time limits, stop conditions, and the accountable approver.
- Build a shared gateway: put authentication, routing, quotas, logging, redaction, and retry policy at one control point instead of embedding them in every application.
- Version every component: model, prompt, tool schema, retrieval corpus, and policy should appear in traces and evaluations.
- Deploy in stages: use shadow or canary runs, compare with the existing process, then expand only against predefined quality, cost, and safety thresholds.
- Exercise failures: test slow providers, failing tools, exhausted quotas, contaminated retrieval data, and interrupted workflows.
Platform-engineering principles still apply. Provide a paved path with logging, quotas, secret management, and observability, as discussed in this article on developer experience and platform engineering. That enables teams to change models or serving backends without duplicating controls.
Limits of the argument
A good harness cannot make an unsuitable model suitable. If a model lacks domain quality, cannot follow a critical format, or fails a regulatory requirement, routing and guardrails can limit harm but cannot create the missing foundational capability.
The harness also has costs: added latency, operational work, integration complexity, and additional failure modes. Small teams do not need a large platform before they have a defined workload. They should begin with a minimal gateway, traces, permission limits, and an evaluation suite; add long-term memory, multi-model routing, or self-hosting only when measurements justify them.
Conclusion: evaluate DeepSeek as a component; operate the harness as a product
The supplied evidence makes DeepSeek a notable part of the changing usage and token-cost picture, but it does not establish a universal choice. The production-grade question is not only, “Which model is cheaper?” It is, “Can the system control, measure, recover, and account for a model-enabled workflow?”
For DeepSeek or any other model, the answer rests in the harness. The model supplies capability; the harness determines whether that capability can be delivered to users with acceptable cost bounds, reliability, and safety.
Sources
- Vercel: DeepSeek overtakes Google on volume, cost per token falls 13.6%
- freeCodeCamp: How to Scale LLM Inference for AI Agents Using vLLM
- Pulumi: Stop Tuning Prompts. Build a Harness.
- Lilian Weng: Harness Engineering for Self-Improvement
- Meta Engineering: From User Sequences to Scaling Laws
- Meta Engineering: GEM Training
- ByteVora: AI infrastructure, GPUs, power, cooling, and data centers
Why developers should care
Model selection affects cost and quality, but the harness determines whether a system can be operated safely, measured meaningfully, and recovered when it fails. Teams should evaluate an entire workflow lifecycle, not token prices or benchmark scores alone.
Recommended action
- 1Within two weeks, implement a minimal gateway for one workflow: request-level traces, token and tool-call limits, least-privilege capabilities, a checkpoint before write actions, and an evaluation suite that includes tool failure and prompt injection. Only then compare DeepSeek with alternatives on cost per successful outcome.