Quick summary
- AWS says Australian teams can access OpenAI GPT-5.6 Sol, Terra, and Luna through Amazon Bedrock from the Sydney and Melbourne Regions using global cross-Region inference. Its guidance also covers prompt caching, OIDC-based Codex authentication, and CloudWatch monitoring, connecting model access to the controls needed for production.
- The option can consolidate OpenAI workloads within an existing AWS platform, but global routing introduces design questions around data handling, identity, observability, latency, and cost that teams must validate themselves.
- Run a non-sensitive pilot from Sydney or Melbourne, evaluate all three models with representative traffic, and complete the data-routing, OIDC/IAM, resilience, and CloudWatch reviews before production approval.
What happened
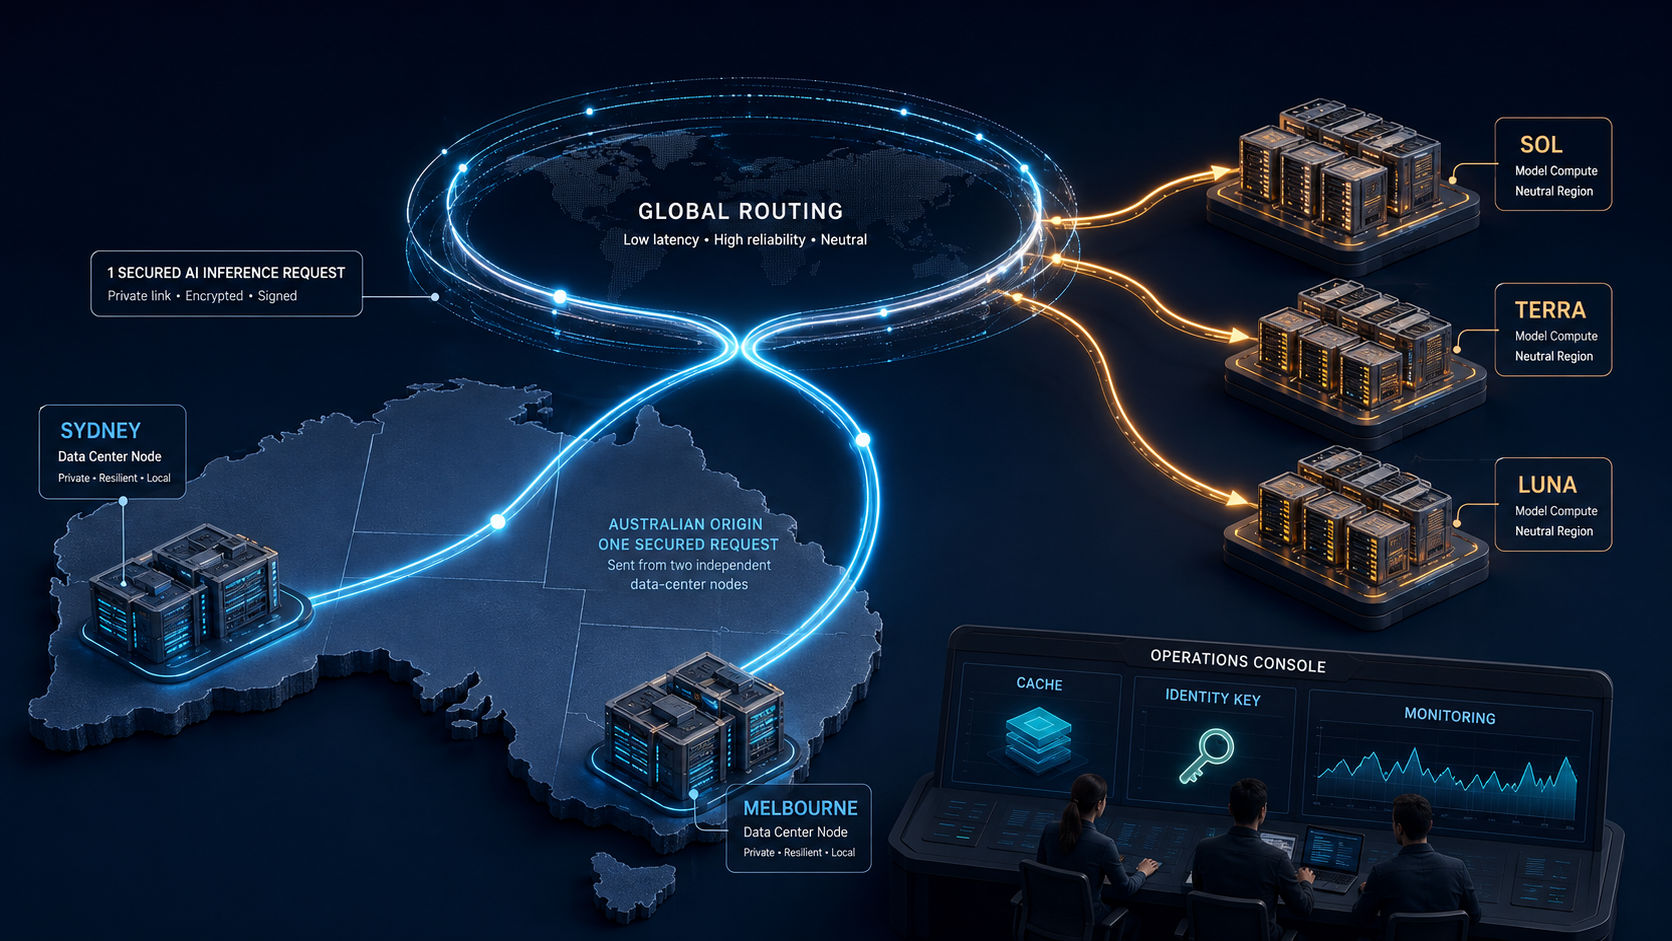
Developers operating in Australia have a new AWS-managed route to OpenAI models. In its technical guide to OpenAI GPT-5.6 on Amazon Bedrock, AWS says Sol, Terra, and Luna can be invoked from Asia Pacific (Sydney) and Asia Pacific (Melbourne) with global cross-Region inference.
The useful part is the end-to-end operational scope. AWS addresses model invocation alongside prompt caching, OpenID Connect authentication for Codex, and usage monitoring in Amazon CloudWatch, giving platform teams a starting outline for more than a one-off API experiment.
What does global cross-Region inference mean for the design?
The application begins from an Australian AWS Region, while Bedrock uses a global cross-Region inference path to serve the request. That distinction matters: the Region from which a workload calls the service should not be treated as proof that every processing step remains in that same geography.
Architecture and security reviews should therefore record both the originating Region and the inference configuration. Teams with data-location obligations need to verify the applicable AWS behavior and their own policy requirements rather than infer a residency guarantee from the words “Sydney” or “Melbourne.”
The supplied AWS material establishes availability through this route, but it does not provide comparative benchmarks for the three models or for Australian workloads. Latency, throughput, error behavior, and cost should consequently be measured with representative prompts and traffic patterns.
Model access is only one layer of the implementation
| Layer | Role | Production question |
|---|---|---|
| Invocation | Reach Sol, Terra, or Luna through Bedrock | Which model and inference configuration fit each workload? |
| Prompt caching | Reuse stable prompt context where supported | Which context is repeated, and does caching produce a measurable benefit? |
| OIDC authentication | Connect Codex through an identity flow | Which identities can assume which permissions? |
| CloudWatch | Observe usage and operational signals | What metrics, logs, alarms, and budget thresholds are required? |
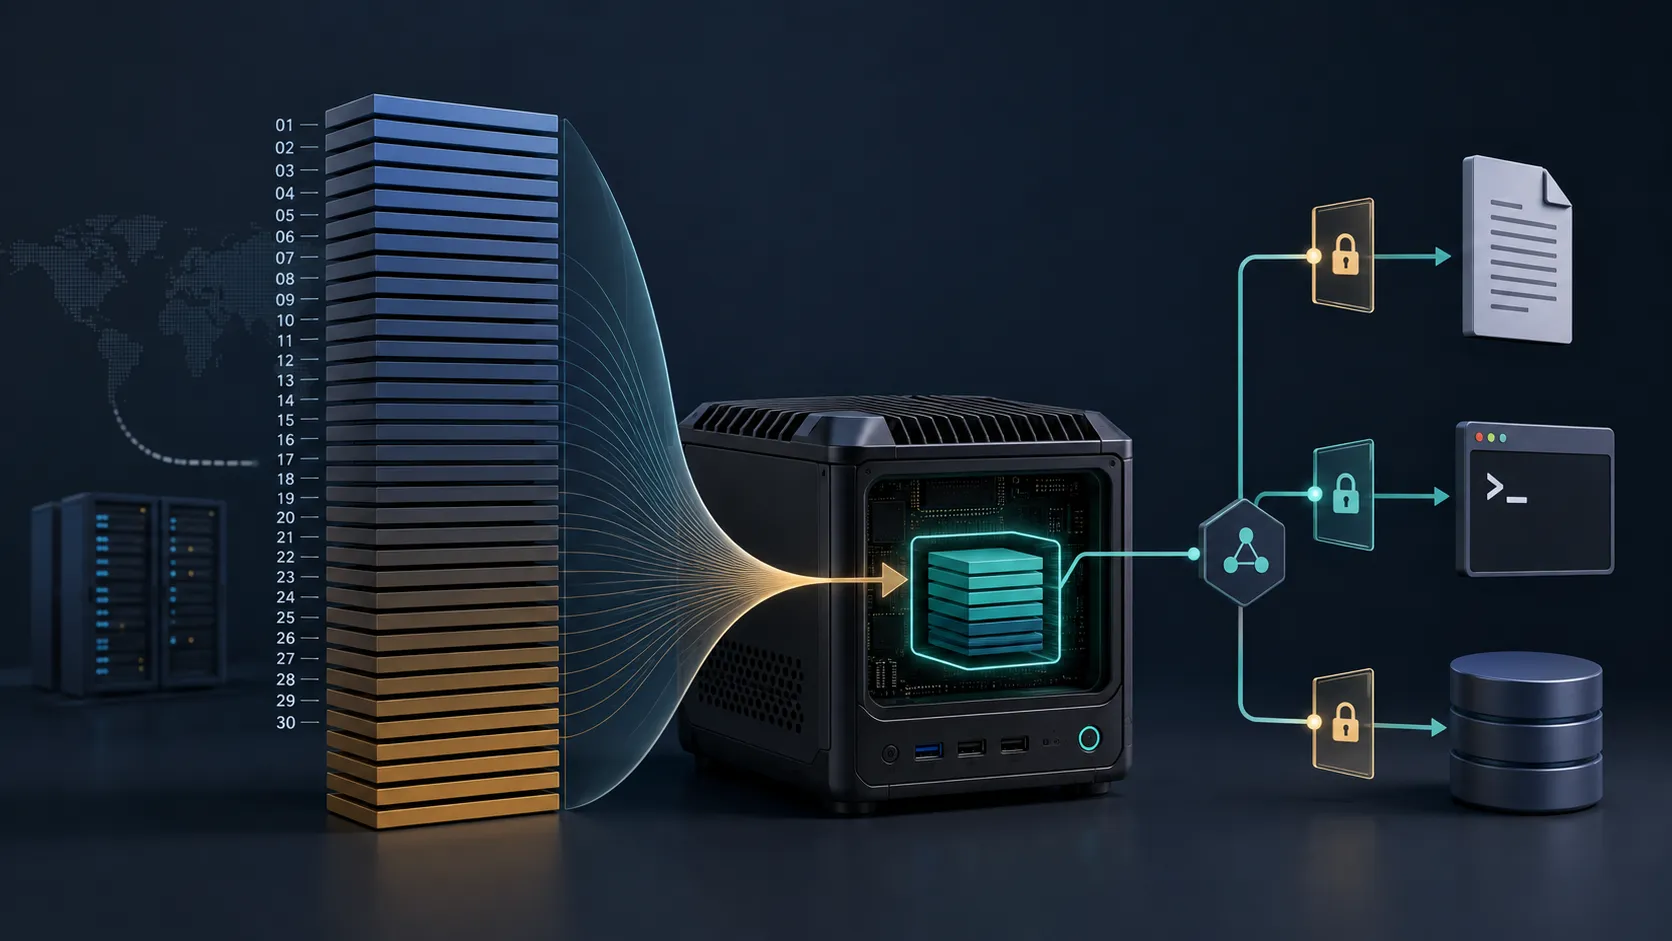
Prompt caching is relevant when requests repeatedly include stable instructions or context. It should still be treated as an optimization to test, not a universal switch: isolate the reusable portion, preserve correctness when context changes, and compare observed behavior before and after enabling it.
OIDC is similarly part of a larger authorization design. Authentication establishes an identity; it does not by itself decide what that identity may do. Codex access should be mapped to narrowly scoped roles, with separate permissions for experimentation, deployment, and production operations where appropriate.
CloudWatch closes the loop only if the team decides what to measure. A useful baseline includes signals for requests, failures, latency, and consumption when those signals are exposed by the integration or collected by the application. Alerts should correspond to an action, such as investigating an error spike or stopping unexpected usage.
How should developers move from a demo to production?
Start with a bounded use case whose quality can be reviewed. A small evaluation set can reveal whether Sol, Terra, or Luna is the better fit for that task without assuming that one model choice will suit every endpoint, agent, or document workflow.
Place the Bedrock call behind an internal service boundary or adapter. This gives the application one place to apply timeouts, retry limits, error normalization, request metadata, and model selection, while keeping business logic from depending directly on a particular model identifier.
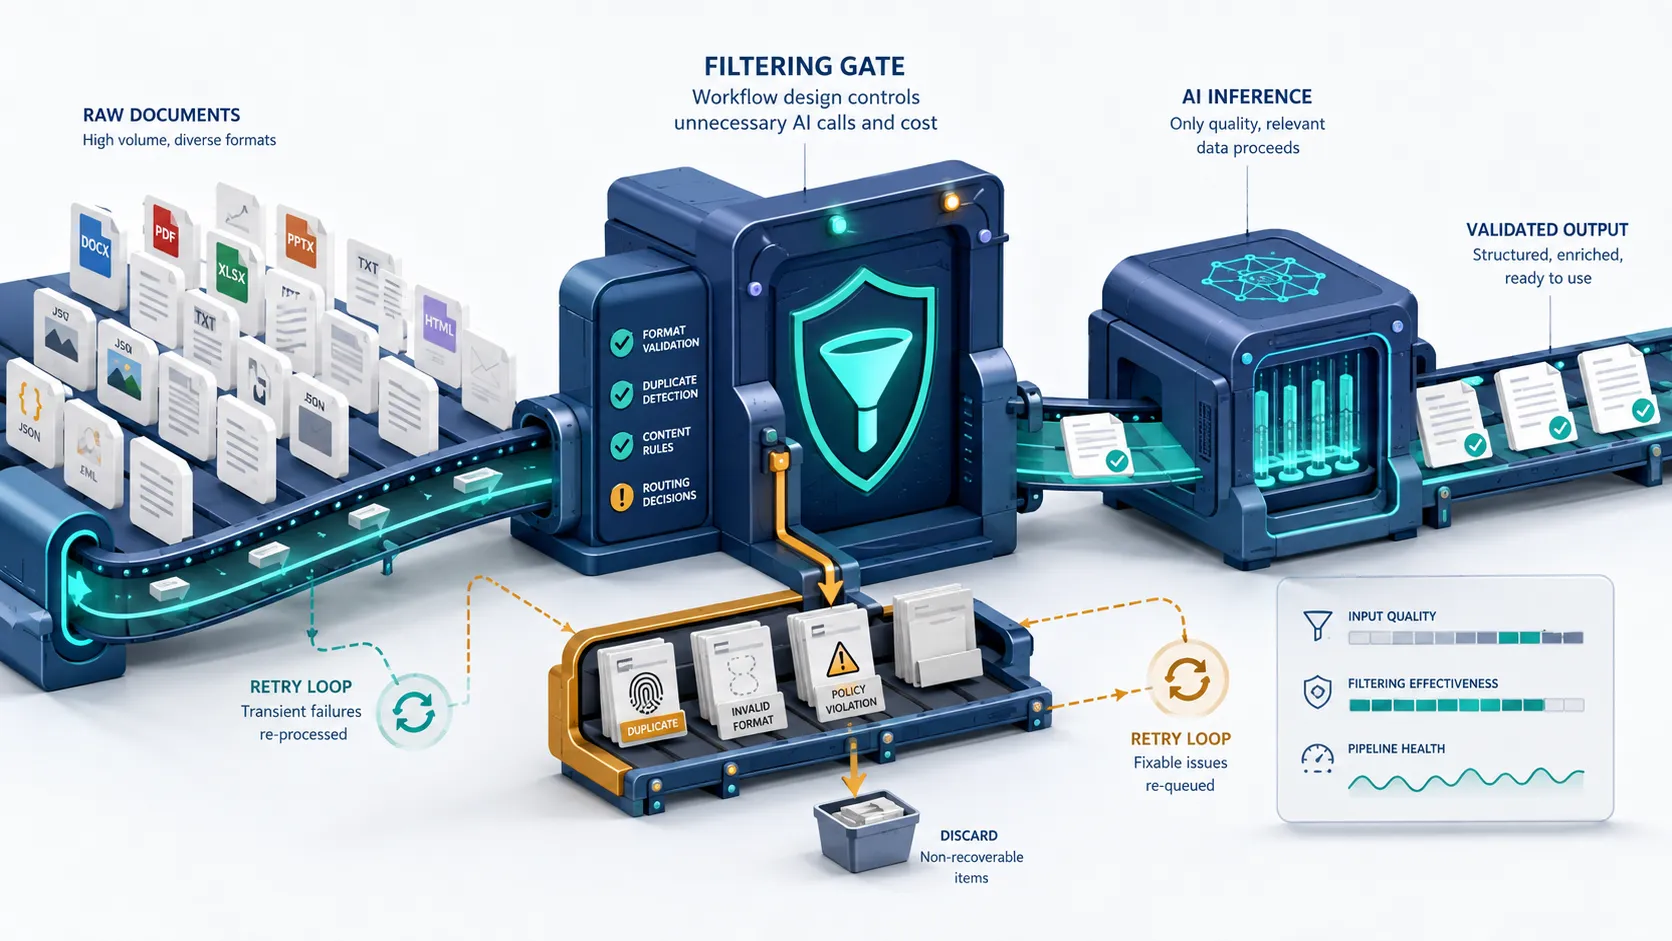
Next, classify the content sent in prompts. Sensitive fields may need exclusion or masking, and log retention should be designed so observability does not create a second copy of data that the primary request path carefully protects. These controls are part of the broader point that machine-learning systems still require explicit governance, regardless of how simple their integration appears.
Reliability also belongs at the application layer. Set bounded retries, define what happens when inference is slow or unavailable, and decide whether users receive a degraded response, a queued job, or an explicit failure. The AWS guide identifies available building blocks; it does not remove the need for workload-specific resilience.
A practical readiness checklist
- Confirm model access and the intended global cross-Region inference configuration in each AWS environment.
- Evaluate Sol, Terra, and Luna with representative inputs and clear quality criteria.
- Review data classification, regional processing requirements, logging, and retention before sending production content.
- Use the OIDC flow for Codex with least-privilege IAM permissions and a documented trust boundary.
- Instrument the application and CloudWatch, then attach actionable alarms to operational and consumption signals.
- Benchmark prompt caching with repeated context rather than assuming a latency or cost outcome.
- Test timeout, retry, throttling, and failure paths under realistic concurrency.
Teams should also verify current service documentation, model identifiers, quotas, and commercial terms during implementation. Those details can change independently of application code and are not fully specified in the supplied announcement summary.
Conclusion
- Bedrock provides an AWS path to GPT-5.6 Sol, Terra, and Luna from Sydney and Melbourne through global cross-Region inference.
- An Australian entry Region should not be mistaken for an unverified data-residency guarantee.
- Prompt caching, OIDC, and CloudWatch form an operational chain rather than unrelated optional features.
- A measured pilot with least-privilege access and explicit data controls is the safest route to production.
Related reading
- AI Functions in the data warehouse: where should low-code ML start?
- No-code machine learning still needs governance controls
- No-code machine learning from Snowflake to predictive dashboards
Source
Accessing OpenAI models on Amazon Bedrock from Australia with global cross-Region inference
Why developers should care
The option can consolidate OpenAI workloads within an existing AWS platform, but global routing introduces design questions around data handling, identity, observability, latency, and cost that teams must validate themselves.
Recommended action
- 1Run a non-sensitive pilot from Sydney or Melbourne, evaluate all three models with representative traffic, and complete the data-routing, OIDC/IAM, resilience, and CloudWatch reviews before production approval.